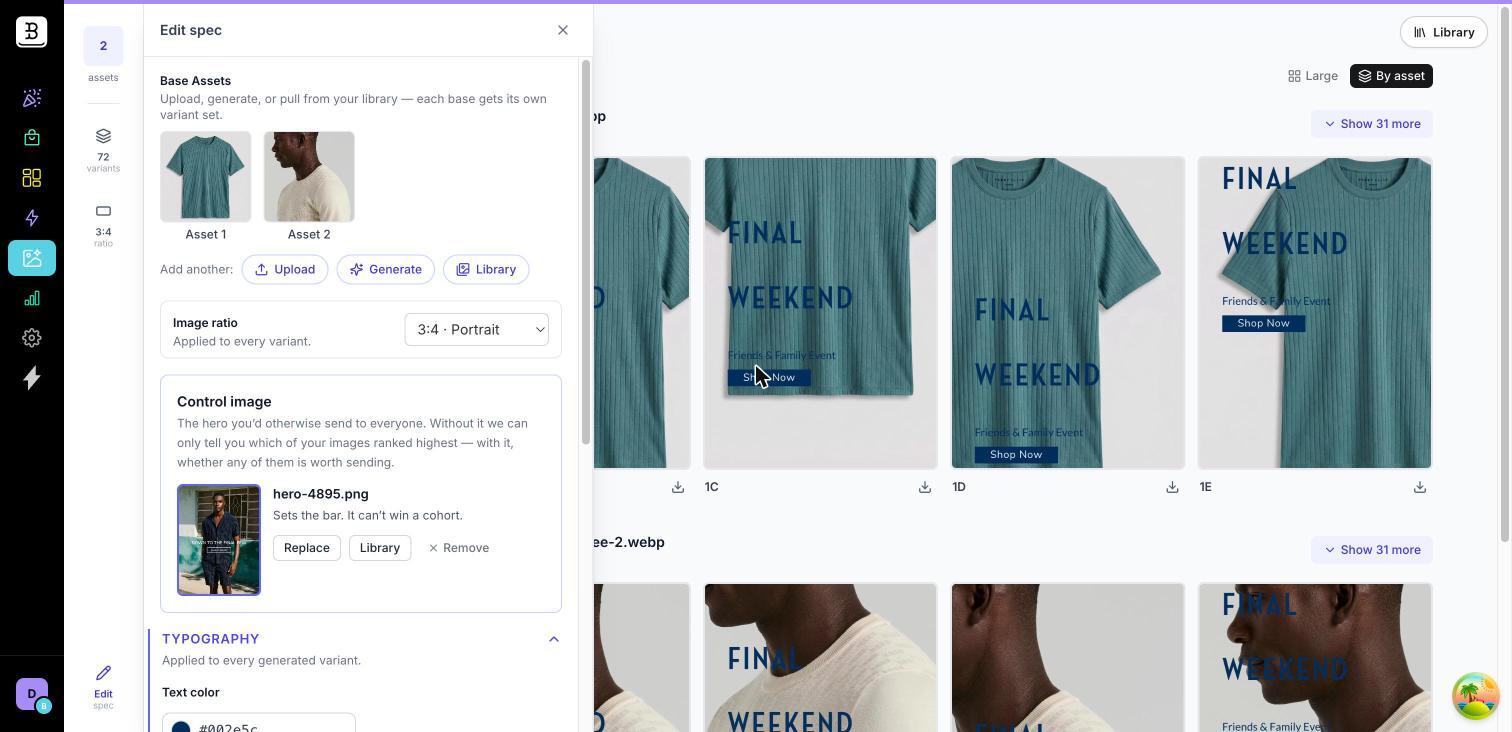
Hero Lab can now tell you whether your personalized heroes are actually worth sending — not just which one "won."
Designate a control — the hero you'd send if you did nothing. It's scored against every generated variant, on the same model and same cohorts, but never competes in the set: it's the bar, not a contestant.
Instead of a leaderboard, you get one verdict: Send the set, One image beat your control, Your control is predicted to win, or No clear winner yet.
"Your control is predicted to win" is a real, useful outcome, not a dead end — common for brands with a strong existing hero. Anything too close to call gets its own group instead of being dressed up as a result.
Also in this release: the tile button now reads "Add to library" instead of "Approve," Hero Lab says "cohort" instead of "segment," and editing an already-saved variant puts it back to draft so you re-add it.
Why it matters: instead of just picking a winner, you find out whether personalizing actually beats what you'd send anyway. This is the Hero Lab half of the Surge feature above.